Search ≠ Training ≠ Agent: Cloudflare Split the Controls — Robauto Data Shows Why
Robauto Team · Published · Last updated
Cloudflare’s Sep 15 Search/Training/Agent controls match OpenAI, Anthropic, and Google bot splits. Robauto’s Sep 23 data: 21.53% headline AI share, ~11% true llm_crawler.
On September 15, 2026, Cloudflare told site owners they no longer have to treat “AI bots” as one switch. The company shipped a Disallow AI Training control beside separate Search, Training, and Agent preferences — so you can stay indexed for search while refusing model training, without a blunt “Block AI” that also kills discoverability.
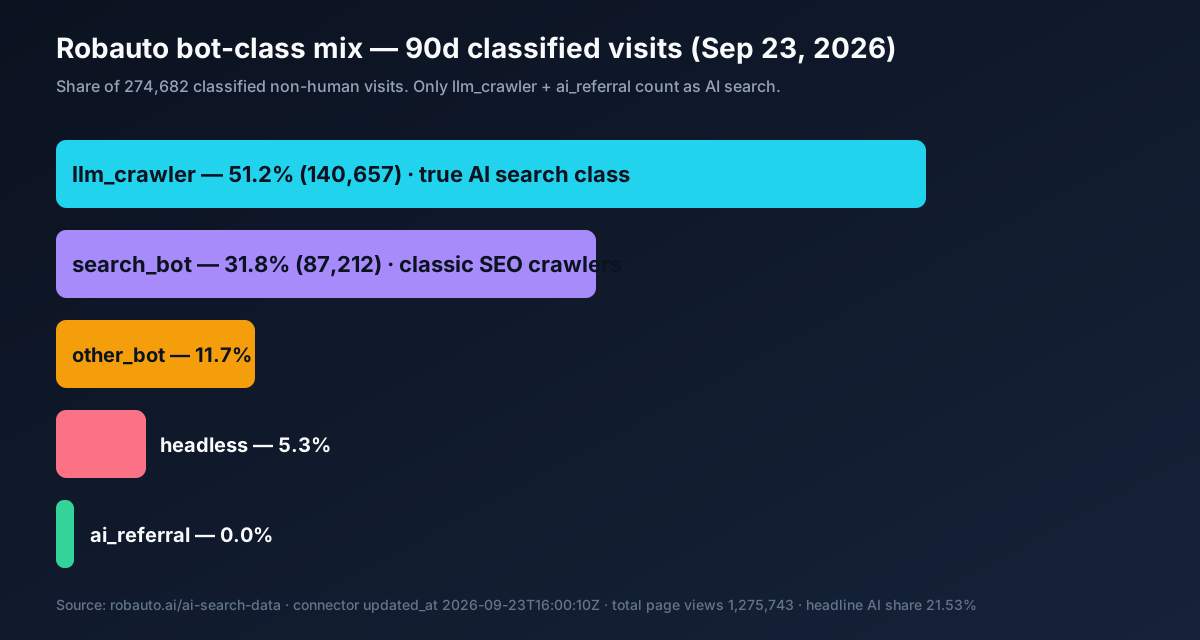
Eight days later, Robauto’s live network still shows why that split matters. The headline number reads 21.53% AI agent share of page views over 90 days. Inside the classified bot mix, only 51.2% is llm_crawler — the class Robauto counts as AI search alongside ai_referral (currently 0%). That is roughly 11.0% of total page views, not 21.5%. The rest is classic SEO crawlers, headless automation, and other non-search agents.
What Cloudflare changed on Sep 15
Cloudflare’s post frames mixed-use crawlers — one bot doing search and training — as the hard tradeoff. The new Disallow AI Training setting publishes a no-training preference (via robots.txt / Bot Preference Sync) while keeping Accountable search crawlers allowed. Block now stops mixed-use crawlers entirely, including Applebot, Bingbot, and Googlebot — search included. Agent controls stay separate because user-directed fetches are not the same policy problem as training.
| Control | Intent | What Cloudflare says | Source |
|---|---|---|---|
| Search | Stay findable in indexes | Less than 1% of Cloudflare sites choose to block Search bots | Cloudflare Blog |
| Training | Opt out of model training | 17% of sites enable some training block; Disallow AI Training keeps Accountable search crawling | Cloudflare Blog |
| Agent | User-directed fetches / browser agents | Separate control; no mature “Disallow Agent” robots.txt standard yet | Cloudflare Blog |
Operators Cloudflare calls Accountable — including Apple, Google, Microsoft, and (with separate search vs training bots) Amazon, Anthropic, Meta, and OpenAI — are expected to honor training opt-outs without collapsing search access.
Vendors already split the user-agents
The Cloudflare UI is catching up to what major AI vendors already document in robots.txt.
| Operator | Search / index | Training / generative opt-out | User-triggered fetch | Source |
|---|---|---|---|---|
| OpenAI | OAI-SearchBot — ChatGPT search results |
GPTBot — foundation-model training |
ChatGPT-User — user actions (not automatic crawl) |
OpenAI crawlers |
| Anthropic | Claude-SearchBot — search quality / indexing |
ClaudeBot — potential training datasets |
Claude-User — live user queries |
Anthropic Help Center |
Googlebot — Search (and related Search surfaces) |
Google-Extended — Gemini / Vertex generative use & grounding (does not control Search ranking) |
— | Google common crawlers |
OpenAI is explicit: allow OAI-SearchBot and disallow GPTBot if you want ChatGPT search visibility without training use. Anthropic’s April 7, 2026 help article separates the same three jobs. Google’s Google-Extended token governs Gemini / Vertex generative use and grounding — not inclusion or ranking in Google Search.
Robauto’s Sep 23 pulse: one headline, five bot classes
Robauto’s public AI Search Data connector (updated 2026-09-23T16:00:10Z) classifies non-human visits into five classes. Only llm_crawler + ai_referral are AI search. Everything else can inflate a naive “AI traffic” KPI.
| Metric | Value | Source |
|---|---|---|
| Total page views (90d) | 1,275,743 | AI Search Data |
| Classified non-human / “AI agent” views (90d) | 274,682 | AI Search Data |
| Headline AI traffic share | 21.53% | AI Search Data |
| llm_crawler visits (AI search class) | 140,657 (51.2% of bot mix) | AI Search Data |
| llm_crawler as % of all page views | ~11.0% | Derived from connector totals |
| search_bot | 87,212 (31.8%) | AI Search Data |
| other_bot | 32,207 (11.7%) | AI Search Data |
| headless | 14,606 (5.3%) | AI Search Data |
| ai_referral | 0 (0.0%) | AI Search Data |
| Top engine in classified mix | Meta AI — 83,636 visits (30.4%) | AI Search Data |
{
  "as_of": "2026-09-23T16:00:10.451+00:00",
  "network_90d": {
    "total_page_views": 1275743,
    "classified_non_human_views": 274682,
    "headline_ai_traffic_percentage": 21.53,
    "true_ai_search_class": {
      "llm_crawler_visits": 140657,
      "llm_crawler_share_of_bot_mix": 51.2,
      "ai_referral_visits": 0,
      "approx_share_of_page_views": 11.0
    },
    "other_classes": {
      "search_bot": {"visits": 87212, "share_of_bot_mix": 31.8},
      "other_bot": {"visits": 32207, "share_of_bot_mix": 11.7},
      "headless": {"visits": 14606, "share_of_bot_mix": 5.3}
    },
    "top_engines_in_classified_mix": [
      {"engine": "Meta AI", "visits": 83636, "share_percentage": 30.4},
      {"engine": "grok_bot", "visits": 27008, "share_percentage": 9.8},
      {"engine": "baiduspider", "visits": 23959, "share_percentage": 8.7}
    ],
    "source": "https://robauto.ai/ai-search-data"
  },
  "leaderboards_2026_09_23": {
    "overall_agent_1": {
      "agent": "Meta External Agent",
      "bot_class": "other_bot",
      "visits_7d": 13983,
      "sites_touched": 1045,
      "source": "https://robauto.ai/agent-leaderboard"
    },
    "llm_crawler_1": {
      "agent": "Bingbot (Copilot)",
      "bot_class": "llm_crawler",
      "visits_7d": 2560,
      "sites_touched": 208,
      "source": "https://robauto.ai/agent-leaderboard"
    },
    "brand_leaderboard_1": {
      "domain": "marketontology.com",
      "agent_visits_7d": 9323,
      "source": "https://robauto.ai/leaderboard"
    }
  },
  "industry_controls": {
    "cloudflare_disallow_ai_training": "https://blog.cloudflare.com/accountable-mixed-use-ai-crawlers/",
    "openai_bots": "https://platform.openai.com/docs/bots",
    "anthropic_bots": "https://support.anthropic.com/en/articles/8896518-does-anthropic-crawl-data-from-the-web-and-how-can-site-owners-block-the-crawler",
    "google_extended": "https://developers.google.com/search/docs/crawling-indexing/google-common-crawlers"
  }
}
Two leaderboards, two stories
Filter the Agent Leaderboard to llm_crawler and the ranking flips away from the overall board.
| Board | #1 agent (7d) | bot_class | 7d visits | Sites touched | Source |
|---|---|---|---|---|---|
| All agents | Meta External Agent | other_bot | 13,983 | 1,045 | Agent Leaderboard |
| llm_crawler only | Bingbot (Copilot) | llm_crawler | 2,560 | 208 | Agent Leaderboard |
| llm_crawler #2 | GPTBot (OpenAI) | llm_crawler | 217 | 65 | Agent Leaderboard |
| llm_crawler #3 | ClaudeBot (Anthropic) | llm_crawler | 99 | 20 | Agent Leaderboard |
Meta AI still leads the 90-day engine mix at 30.4% of classified visits. Meta External Agent leads the agent board as other_bot. Those are related brands with different jobs — the same distinction Cloudflare’s Agent vs Training vs Search controls are trying to make operable for publishers.
On the Brand Leaderboard, marketontology.com remains #1 with 9,323 agent visits over seven days. Visits still do not equal readiness; yesterday’s scans put that leader at score 24 while a lower-traffic peer hit 100. Measure attention and capability separately.
A practical robots.txt posture this week
- Decide three policies, not one. Search visibility, training use, and live agent fetch are different outcomes. Cloudflare’s UI and vendor-specific user-agents now let you express them separately.
- If you want ChatGPT search without training, allow
OAI-SearchBotand disallowGPTBot— OpenAI documents those as independent. - If you want Claude search / live answers without training, keep
Claude-SearchBot/Claude-Userallowed and disallowClaudeBotfor training opt-out. - If you want Google Search but not Gemini generative use, use
Google-Extended— Google states it does not affect Search ranking or inclusion. - On Cloudflare, prefer Disallow AI Training over a blunt Block when you still need Applebot / Bingbot / Googlebot for search. Block is now an explicit “stop search too” choice for mixed-use crawlers.
- In analytics, report
llm_crawler(+ai_referral) as AI search. Keepsearch_bot,headless, andother_boton a separate line so Ahrefs, Yandex Render, and Meta External Agent do not inflate your AEO narrative.
What this means for builders
Cloudflare’s September 15 controls make Search, Training, and Agent first-class policy knobs. OpenAI, Anthropic, and Google already expose matching robots.txt tokens. Robauto’s September 23 network snapshot shows the measurement side of the same story: a 21.53% headline AI share compresses to about 11.0% of page views once you keep only the llm_crawler class. Split the controls. Split the KPIs. Then optimize for the outcome you actually want — citation, training refusal, or live agent action — instead of a single “AI traffic” number that hides three different jobs.
Sources
- Cloudflare: Disallow AI Training / Accountable mixed-use crawlers
- OpenAI crawlers overview
- Anthropic: ClaudeBot, Claude-User, Claude-SearchBot
- Google common crawlers (incl. Google-Extended)
- Robauto AI Search Data
- Robauto Agent Leaderboard
- Robauto Brand Leaderboard
- Prior Robauto post: Agent Visits ≠ Agent-Ready
Where can an agent get this data live?
Robauto MCP — Agent Intelligence & Brand Discovery Infrastructure. A public, stateless Streamable HTTP endpoint at https://mcp.robauto.ai/mcp, callable with no key. Setup and the full tool list are in the Robauto MCP directory.